AI Search Visibility
Monitoring Generative AI Search Results: API vs Scraping
Tools for monitoring generative AI search results collect answers by API or interface capture, and the choice changes accuracy and cost. Here is how to test it.
 Simran Rawat16 Nov 202611 min read
Tools for monitoring generative AI search results send a fixed list of prompts to AI engines on a schedule, record the answer text, the brands named and the sources cited, then report trends. They collect answers either through official APIs or by capturing the consumer interface. The method changes how closely the data matches what real users see, and what the tool costs to run.
Tools for monitoring generative AI search results work by asking AI engines the same set of questions on a schedule, saving each answer, and extracting which brands were named and which pages were cited. The collection method matters: some tools call an engine's API, others capture the answer from the consumer interface. That choice affects accuracy, coverage and price, so it is the first thing to ask any vendor.
Key takeaways
- There are two main collection methods: API-based collection and interface capture (often called scraping). Each trades fidelity to the real user experience against stability and cost.
- A tool's answers are only as good as its prompts, its repeat runs and its entity matching, not just the engine it queries.
- Ask every vendor how each engine is collected, whether a logged-in or location-specific session is used, and how often prompts are re-run.
- Run a three-day trial test: compare the tool's captured answer against a manual check of the same prompt, and score the match.
- Treat a single answer as a sample. Trends across repeated runs are the signal.
How do tools monitor generative AI search results?
Every monitoring tool follows the same four-stage loop. It holds a prompt list, runs each prompt against each engine, stores the full answer with its citations, and then parses the answer for brand mentions, position and sources. Dashboards, share-of-voice scores and alerts are built on top of that stored data.
The differences between vendors sit almost entirely in stage two: how the answer is obtained. Everything downstream, including charts and recommendations, inherits the quality of that capture.
The four-stage loop
- Prompt set: a list of questions a buyer might ask, grouped by topic and funnel stage.
- Collection: each prompt is sent to each engine, by API or by capturing the interface.
- Storage: the answer text, cited URLs, and the date and engine are saved.
- Analysis: mentions, sentiment, position and cited domains are extracted and compared with competitors.
For a deeper look at choosing the prompts themselves, see which prompts to track for AI search visibility and how many prompts you need.
What is the difference between API collection and interface capture?
API collection sends a prompt to an engine's developer endpoint and receives a structured response. Interface capture loads the consumer product, such as the chat window or search page, submits the prompt as a user would, and records what is rendered. The seoClarity article on this topic describes UI scraping as mirroring what real users see and API monitoring as a simplified, developer-facing version (seoClarity). Note that seoClarity sells tooling and argues for one side, so treat its framing as a vendor view rather than a neutral finding.
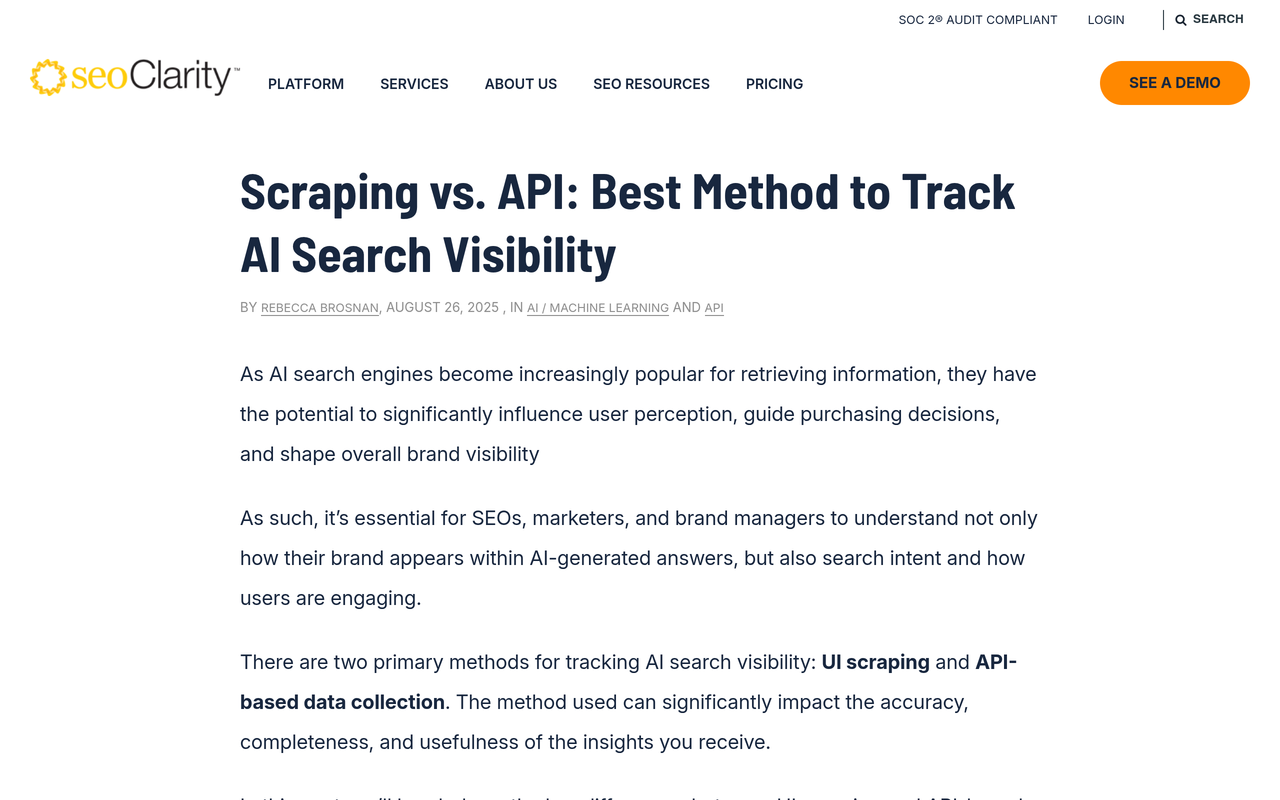
The same article notes that the ChatGPT interface includes additional logic and response handling that is not reflected in the API (seoClarity). That is the core accuracy concern: an API answer and a chat answer to the same question can differ, because the product around the model is not identical to the model endpoint.
| Factor | API collection | Interface capture |
|---|---|---|
| Closeness to what a user sees | Can differ from the consumer product, because the endpoint is not the full product | Closer, because the rendered consumer answer is recorded |
| Stability | Structured and predictable; changes are versioned and documented | Can break when the interface layout or defences change |
| Citations and sources | Depends on whether the endpoint returns them | Usually the same sources the user sees |
| Session control (location, login) | Limited to the parameters the API exposes | Can be set to mimic a real session, at extra cost |
| Cost to run | Pay per call; predictable per prompt | Needs browser infrastructure, proxies and maintenance |
| Terms of service risk | Within the provider's published terms | Check each provider's terms; this is a vendor risk to ask about |
Which method is more accurate?
Neither method is automatically accurate. Interface capture is closer to the consumer answer in principle, but a poorly maintained capture can record partial pages, error states or the wrong region. API collection is cleaner data, but it can answer a slightly different question than the one your customer sees.
Accuracy is also a property of the whole pipeline. A tool that runs each prompt once will show noise as if it were change, because generative answers vary between runs. A tool that parses brand names loosely will miscount mentions of similar names. Both problems appear regardless of collection method, which is why the questions below go beyond the API-versus-scraping label.
Noma by Nurdd is an AI search visibility dashboard that tracks whether a brand appears in answers from 13 AI engines, including ChatGPT, Gemini, Perplexity and Claude, polled daily. It records whether the brand is named and which page each citation comes from, so teams can check the data against their own manual searches.
Why does the collection method change cost?
Cost has three parts: the cost of each answer, the number of answers needed, and the cost of keeping collection working. API calls are billed per request, so cost scales with prompts, engines and run frequency. Interface capture adds browser sessions and maintenance, so vendors usually pass that on as higher plan prices or tighter prompt limits.
Worked example: counting answer captures
This is arithmetic on a hypothetical setup, not a vendor price. Suppose a team tracks 25 prompts across 13 engines, polled daily for 30 days. That is 25 × 13 × 30 = 9,750 answer captures a month. If a vendor also runs each prompt three times per day to smooth out variation, the figure becomes 29,250.
The point of the exercise is to ask what the vendor's plan assumes. A plan that counts only prompts may hide how many engines, runs and days sit behind each prompt. Ask for the unit, then multiply.
| Question to put to the vendor | Why the answer changes your cost |
|---|---|
| Is the price per prompt, per engine or per answer? | Per-engine pricing multiplies quickly across 13 engines |
| How many times is each prompt run per day? | More runs reduce noise but raise cost |
| Are all engines included in every plan? | Engine add-ons raise the real price |
| Are there overage charges? | Prompt growth is common once teams see value |
For published pricing across vendors, see software for AI search visibility pricing.
Are AI visibility tool results accurate?
They are accurate enough to show direction, and accurate enough to act on when you verify them. They are not a census of every answer a user will ever see. Generative answers can vary between runs, between sessions and between locations, so a visibility score is an estimate drawn from a sample of prompts.
Personalisation is one reason. Whether answers shift for different users is covered in does personalization change AI answers. The practical rule: trust week-over-week movement across many prompts more than any single answer, and verify a sample by hand.
What should you ask an AI visibility vendor?
Ask questions that force specifics. A vendor who understands its own pipeline can answer each of these in a sentence. A vague answer is information too.
- For each engine, do you collect through an API or by capturing the interface?
- Do you record the full answer text and the cited URLs, or only a mention flag?
- Can I open the stored raw answer behind any number on the dashboard?
- How many times is each prompt run, and how do you handle variation between runs?
- Can answers be collected for a specific country or language?
- How do you match brand names, and how do you handle similar names and misspellings?
- How do you tell me when an engine changes its interface or response format?
- What happens to my historical data if I leave?
More vendor questions are in AI search visibility software demo: 10 questions to ask and the vendor questionnaire. For a wider verification method, read how to verify AI search tool data before you trust it.
Decision table: which method fits which need
| Your priority | What to look for |
|---|---|
| Matching the consumer answer as closely as possible | Evidence of interface-level capture and visible raw answers |
| Stable, auditable data for reporting | A clear description of each engine's collection and a change log |
| Broad engine coverage on a budget | Transparent per-answer unit costs and included engines |
| Local or language-specific answers | Explicit country and language settings per prompt |
| Citation source analysis | Stored cited URLs per answer, not only brand mentions |
How do you test Noma's data during the free trial?
Noma has a 3-day free trial. A card is taken at signup and billing starts on day 3; cancel before then and you are not charged. Three days is enough for a focused accuracy test if you plan it before you sign up.
The three-day accuracy test
- Day 0, prepare: write 10 prompts a buyer would ask, three about your category, three comparing you with competitors, and four about specific needs. Keep the exact wording.
- Day 1, capture: add the prompts and your brand and competitors to Noma. Then run the same 10 prompts by hand on ChatGPT, Gemini, Perplexity and Claude, saving screenshots and cited links.
- Day 2, compare: for each prompt and engine, check whether the brand named in Noma matches your manual result, and whether the cited pages match. Score each pair as match, partial match or mismatch.
- Day 2, repeat: rerun five prompts manually twice more. If your own results vary, expect the tool to vary too, and note which differences are natural variation.
- Day 3, decide: calculate the match rate, then look at whether the recommendations are tied to specific pages. Cancel before billing starts if the data does not hold up.
Expect partial matches. Two manual runs of one prompt will not always agree, so judge Noma on whether its record falls within the range you saw by hand, not on whether it equals one run. A broader trial plan is in AI visibility tool trial: what to test in 3 days.
Noma is the AI search visibility product from Nurdd, built to show which of 13 AI engines name a brand and which sources they cite, with competitor comparison and recommendations. It belongs in this comparison because a daily record, with the cited page behind each result, gives you something concrete to verify rather than a score to take on trust.
Book a demo at https://www.nurdd.club/demo to see how Noma records answers for your own brand, your competitors and your prompt list, and ask the collection questions above live.
What is a checklist for evaluating any monitoring tool?
- Confirm, in writing, how each engine is collected.
- Ask to see the raw stored answer for three of your prompts.
- Check that cited URLs are stored per answer.
- Confirm run frequency and how variation is handled.
- Check country and language controls if you sell in more than one market.
- Multiply the plan's unit by engines, runs and days to find the true cost.
- Test match rate against manual checks before you commit.
- Ask about data export and retention.
If you are not sure your site is ready to be cited at all, run the GEO readiness scorecard first.
What are the common mistakes when monitoring AI answers?
- Reading one answer as a result. A single run is a sample, so track trends over weeks.
- Tracking branded prompts only. Buyers ask category questions, and those show whether you are discovered.
- Ignoring cited sources. The pages engines cite show where to work, as covered in AI search visibility analysis.
- Comparing tools on engine count alone. Collection method, run frequency and matching quality matter as much.
- Skipping Google's own surfaces. AI Overviews need their own checks; see how to monitor Google AI Overviews.
- No manual spot-check. Without it, errors in collection go unnoticed.
How does monitoring compare with manual checking?
Manual checking is free and useful for a handful of prompts, but it does not scale to many prompts, engines and days, and it records no history. Software supplies the scale and the trend line. The sensible approach is both: software for the record, manual checks for verification. The trade-offs are laid out in manual prompts versus software.
What should you do with the data once you have it?
Monitoring only pays back when it becomes tasks. Look for prompts where competitors are named and you are not, find the pages being cited, and decide whether to improve your own page or earn a mention on the cited source. The process is covered in the AI visibility action plan, and reporting cadence in how to build a monthly AI search metrics report. For tool shortlists, see best AI search monitoring tools and the Noma vs Peec AI comparison. If you want help acting on the findings, Nurdd's generative engine optimization services use Noma to measure the work.
How we researched this
We reviewed a vendor's public explanation of API versus interface-based monitoring and Nurdd's own product facts, and we checked them on the publication date. We did not run hands-on tests of rival tools, interview customers or collect our own data. Because the main external source is written by a vendor that sells interface capture, we used it only for the description of the two methods and flagged that bias. The cost example is simple arithmetic on a hypothetical setup, not a published price. Where a number could not be verified, we left it out.
Next step: see your own data
The fastest way to judge any tool is to compare its record with answers you can check yourself. Book a demo at https://www.nurdd.club/demo and you will see how Noma tracks your brand and competitors across 13 AI engines, which pages are cited, and what to fix first. You can also read more on Noma.
Frequently asked questions
How do tools monitor generative AI search results?
They run a fixed list of prompts against AI engines on a schedule, store each answer with its citations, and extract brand mentions and cited sources. Collection happens through APIs or by capturing the consumer interface. Dashboards then show trends and competitor comparisons.
Are AI visibility tool results accurate?
They are reliable for direction, not for any single answer. Generative answers vary between runs, sessions and locations, so scores are estimates from a sample. Verify a sample by hand and rely on trends across many prompts.
Is API collection or scraping better?
It depends on your priority. Interface capture is closer to what users see, while API collection is more stable and predictable. Ask each vendor which method they use per engine and test the output against manual checks.
Why do tool results differ from what I see in ChatGPT?
Differences come from the collection method, personalisation, location and natural variation between runs. An API response may not reflect all the logic in the consumer product. Compare several runs before deciding the tool is wrong.
How many engines should a tool cover?
Cover the engines your buyers use. Noma tracks 13 AI engines, including ChatGPT, Gemini, Perplexity and Claude. Breadth helps only if each engine's data is collected and stored well.
How often should prompts be re-run?
Daily polling shows trends sooner, and Noma polls daily. Whatever the cadence, judge change across weeks rather than days, because single-day moves are often noise.
Can I test Noma before paying?
Yes. Noma has a 3-day free trial. A card is taken at signup and billing starts on day 3, so cancel before then if you do not want to continue.
Do I still need manual checks?
Yes. Manual checks verify the tool and catch collection problems. Run a small set of prompts by hand each month and compare them with the dashboard.